Speaker Diarization in Overlapping Speech
Current systems drop overlapping speech or misassign it, but real meetings are nearly half overlap.
Speaker diarization, the task of assigning the right words to the right speaker, runs on a structural assumption that fails the moment real people start talking over each other. Most commercial systems still build on a clustering approach that assigns every frame of audio to exactly one speaker. When two voices land in the same frame, the system has to choose one of them, and whatever the other person said simply disappears from the output. This is a design choice made at the architecture level, and it shapes everything downstream.
The task is really two jobs stapled together. A diarization system first has to figure out how many distinct speakers are in the room, then draw the time boundaries that say where one person stopped talking and another started. Get the speaker count wrong and the boundary-drawing step inherits that error. Get the boundaries wrong and the count becomes unreliable too, since the system may split one speaker into two clusters or merge two speakers into one. The two jobs compound each other's mistakes rather than operating independently.
This gap does not appear in the version of diarization that gets demoed. On a clean two-person call with generous pauses, the acoustic signal practically labels itself; that is the demo every product shows, and it is a fair demo in the narrow sense that it is not staged, but it is not what a four-person meeting sounds like, and the gap between the two is where the real engineering problem lives.
How much overlap appears in real meeting audio
Overlapping speech at scale is what gets lost in product pitches. Overlapping speech in real meeting recordings is close to a routine feature of the audio itself, not an occasional glitch to be smoothed over. The AliMeeting corpus, built for the M2MeT Challenge, shows average speech overlap ratios reaching 42% of total audio duration under training conditions. Nearly half the audio in that corpus has more than one person talking at once. A system tuned only on clean, single-speaker frames is mismatched with the actual input it will face in production.
The pattern holds across other benchmarks too. Data from the SmartGlasses Challenge 2026 shows that multi-party meeting recordings carry an overlap ratio roughly twice that of two-person dialogues. Adding speakers to a conversation does not just add more turns to track.
Room acoustics make the problem worse before the overlap-handling even begins. In a typical conference room, with a single microphone sitting in the middle of the table and speakers several feet away, reverberation blurs the acoustic signature a system relies on to distinguish one voice from another. That degraded signal is what the system must then use to split overlapping voices apart, so poor signal quality and the task of assigning speakers compound each other. A product that posts strong numbers on a clean benchmark can still be failing across a large share of the audio in any real conference room. The question that follows is what systems actually do when they encounter this, given that ignoring the overlap isn't an option.
The three ways current systems handle overlapping segments
Three approaches dominate how production systems deal with overlapping speech, and each one trades one kind of error for another rather than eliminating the problem.
The first is masking: detect the region where voices overlap and exclude it from the clustering process entirely, so it cannot corrupt the speaker embeddings used to tell voices apart. This keeps speaker labels cleaner on the parts of the recording the system does process, but it comes at a direct cost: every word spoken during the masked region is dropped from the output. Those dropped words are often the ones that carry the most weight in a conversation, the interruption, the objection, the correction that changes the meaning of what came before it.
The second is nearest-neighbor assignment, which assumes at most two people are speaking at once in any overlapping region and assigns that segment to whichever two speakers were talking immediately before and after it in the timeline. The ByteDance system submitted to VoxSRC-21 used exactly this method: it detected overlapped segments with a model trained on DIHARD3, AMI, and VoxConverse, used pyannote 2.0 separately for voice activity detection, then assigned each overlap to the two closest speakers in time. That system reached a diarization error rate of 5.15% on the VoxSRC-21 evaluation set and placed second in the diarization track. The approach works reasonably well as long as the two-speaker assumption holds, but it degrades as more than two people talk at once or as individual turns get shorter.
The third is target-speaker extraction, which routes overlapping regions to a separate module that tries to isolate each speaker's individual signal before handing it to the speech recognizer. The tttAI system built for the SmartGlasses Challenge 2026 used a WeSep-based extraction model with ECAPA-TDNN speaker conditioning, and fell back to assigning the overlap to whichever speaker was dominant when the extraction itself proved unreliable. That fallback points to the method's central weakness: feeding poorly separated overlapping speech into a speech recognizer produces duplicated word hypotheses and more insertion errors in the transcript, so the extraction step has to work well or it makes the output worse rather than better. Some systems avoid locking into one method. The system that placed first in the MISP 2025 Challenge calculated the proportion of overlapping speech present in each meeting and routed low-overlap recordings to a traditional VBx clustering method while sending high-overlap recordings to an end-to-end segmentation model instead, choosing its architecture based on the audio in front of it rather than applying one fixed pipeline to everything.
Both the BUCEA system at VoxSRC-22 and the ByteDance system at VoxSRC-21 used a tool called DOVER-Lap to combine the outputs of multiple systems run at different time scales, on the logic that coarser time scales produce more robust speaker clustering while finer time scales produce more accurate boundary placement, with overlap handling applied afterward as a post-processing step.
The architectural shift of end-to-end integration of diarization and ASR
The deeper fix being pursued in current research is to stop treating diarization and transcription as two separate steps joined by a hand-off, and instead train a single model to do both jobs jointly. In a cascaded pipeline, the kind described above, diarization errors flow straight into the speech recognizer and then into summarization, and none of the later stages has any way to go back and correct a mistake made upstream. Joint modeling changes that relationship: a model that learns speaker identity and spoken content together can use each one as a signal to improve the other, rather than finalizing speaker labels before a single word has been transcribed.
NVIDIA's Sortformer, presented at ICML 2025, is a concrete example of this direction. It bridges timestamps and tokens for seamless integration of speaker diarization and ASR. The MISP 2025 Challenge, held at Interspeech 2025, pushed the same idea further by adding a second modality entirely: its Audio-Visual Speaker Diarization task incorporated lip movement and other visual cues alongside the audio stream, and the system that won that task reached a diarization error rate of 8.09%, more than seven percentage points better than the baseline. Giving a model video of who is moving their mouth, not just the audio, is a direct way to resolve exactly the ambiguity that trips up audio-only clustering during overlapping speech.
None of this means joint modeling has solved overlap. These are research-stage results on specific benchmarks, and a model trained on one meeting corpus, one accent distribution, or one language mix does not automatically perform the same way on a different one without further fine-tuning. The honest claim is narrower and still significant: integrating diarization and transcription into one process removes the specific interface where cascaded errors used to accumulate unchecked, which is a different achievement than eliminating error. What that means in practice becomes clear once the benchmark numbers are read carefully rather than taken at face value.
Where benchmark error rates stand
The field's headline metric, Diarization Error Rate, measures something real but not everything that matters for a meeting transcript. DER weights every error by how many seconds of audio it covers. A back-channel utterance like "yep," "right," or "wait, what?" typically lasts a few hundred milliseconds, so misattributing it to the wrong speaker barely moves the DER score at all. A system can post an excellent DER and still be getting every one of those short reactions wrong, consistently, without the metric ever reflecting it.
That gap matters because those short utterances are frequently the most informative part of a meeting. A back-channel is how a listener signals agreement, confusion, or quiet pushback in real time, and those are precisely the signals a meeting summary needs to capture correctly if it is going to represent what actually happened in the room. A metric built around total seconds of audio has no mechanism for weighting a two-second interruption as more important than two seconds of silence.
Far-field recording conditions make the underlying speech recognition problem harder in ways that compound with diarization error rather than sitting apart from it. Clean audio, the kind captured close to a single speaker's mouth, lets leading automatic speech recognition models reach word error rates of roughly five to seven percent, with the strongest models dropping under three percent on idealized read-speech benchmarks like LibriSpeech test-clean. Real meeting conditions, with overlapping speakers and background noise, push that rate to twelve percent or higher, and far-field recordings, the conference-room-microphone scenario described earlier, can push word error rates past thirty-five percent. None of this makes the field's progress meaningless. It does mean a benchmark slide showing a strong DER number is answering a narrower question than it appears to be answering, and the output of that same system still has to travel through a pipeline that will treat its speaker labels as ground truth.
How diarization errors compound through the meeting intelligence pipeline
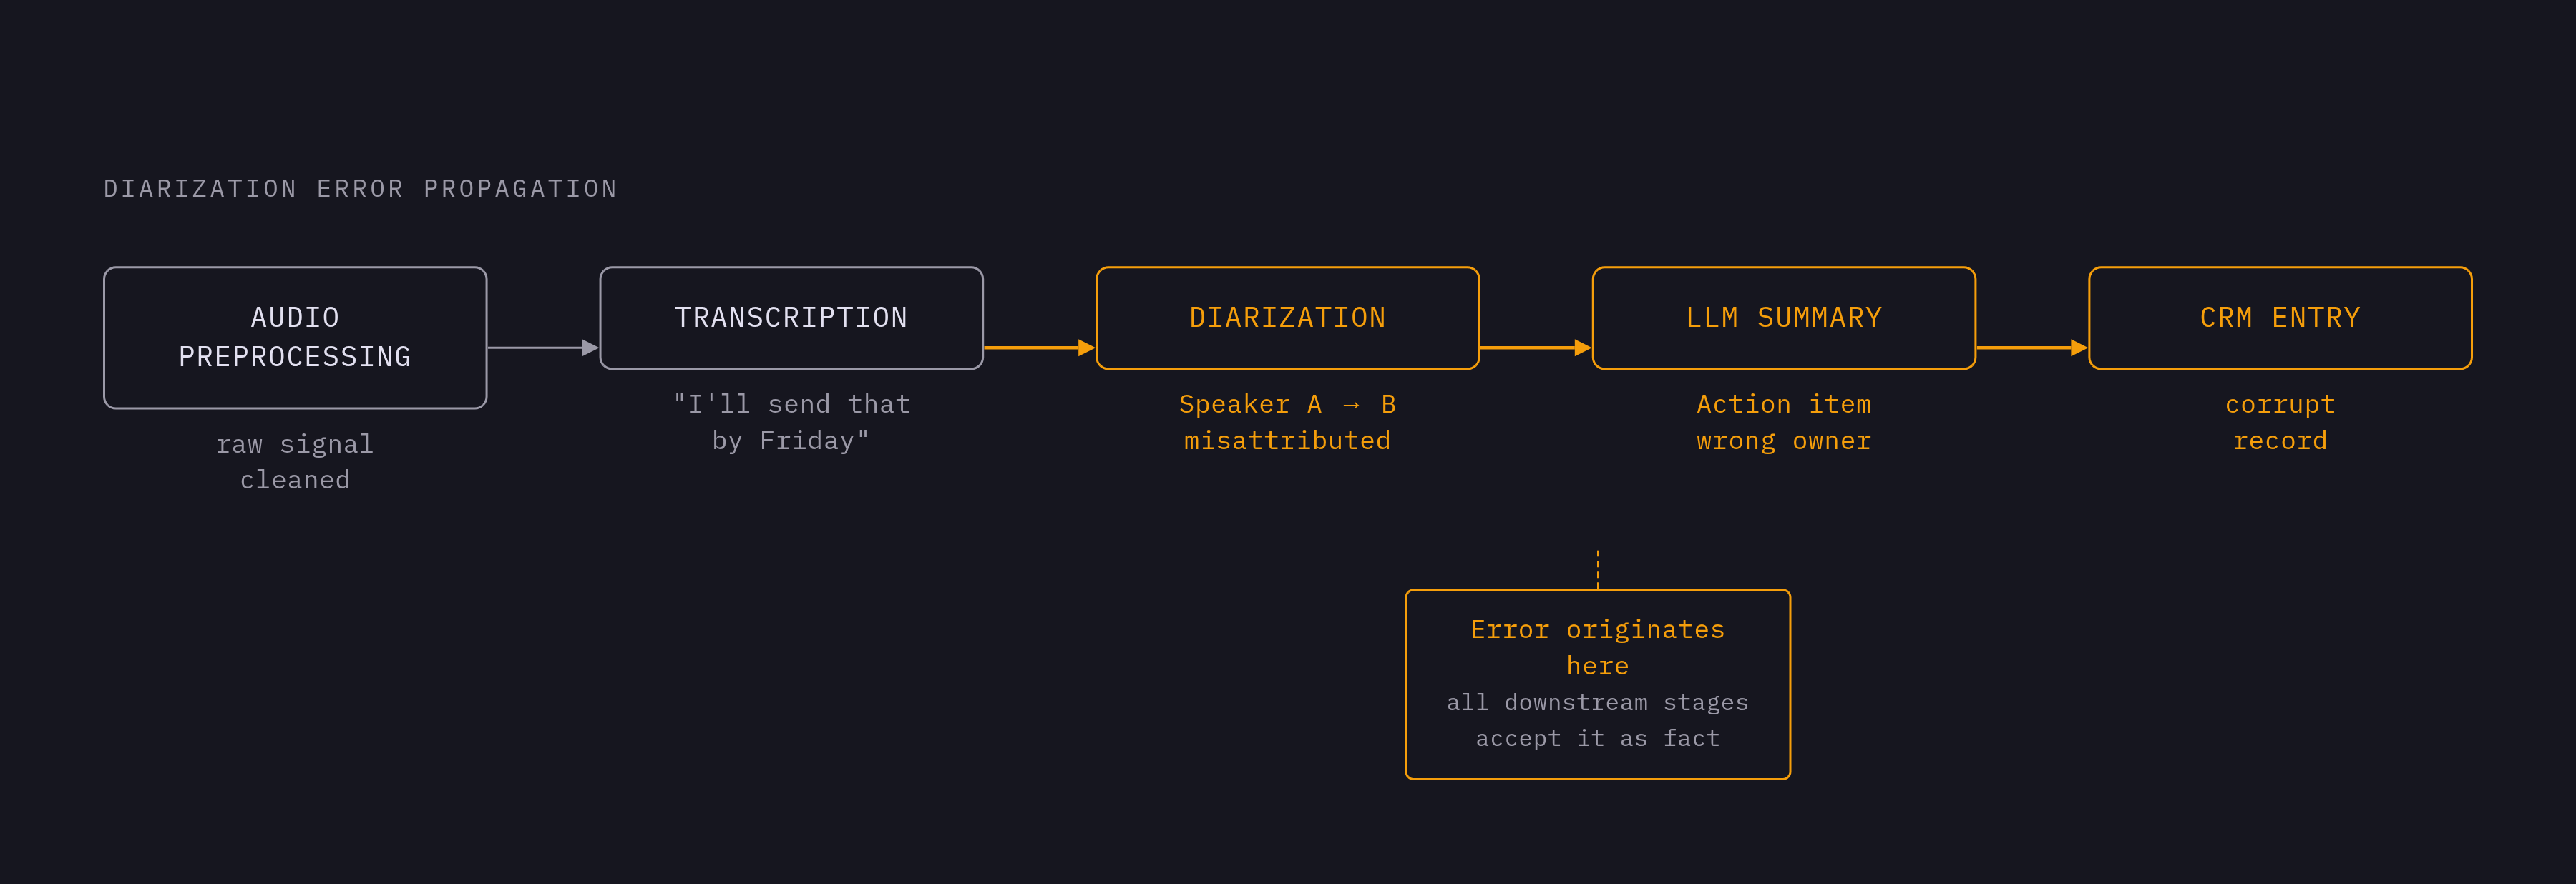
A diarization mistake made early in an AI meeting tool's pipeline does not stay contained to that one stage. It propagates through transcription, through summarization, and into whatever action items or notes the system generates, producing a final output that reads as confident and clean while being wrong in ways that are difficult to catch after the fact. The standard architecture runs through four stages, audio preprocessing, transcription, diarization, and LLM summarization with action-item extraction, and each stage simply takes the previous stage's output as settled fact rather than something to be checked.
The practical failure mode is specific and recognizable. A speaker confusion error means the wrong person gets credited with a commitment: "I'll send that by Friday" attributed to the listener instead of the person who actually said it, which changes who owns that action item for everyone who reads the summary afterward. Summarization then adds its own layer of judgment on top of an already-flawed input. Meeting summarization is fundamentally a relevance problem, deciding what mattered among decisions, commitments, and disagreements, rather than a simple compression problem, and that judgment cannot be made correctly if the speaker labels feeding into it are already wrong.
Sales workflows carry a particular version of this exposure. Misattributed speaker turns in a sales call mean misattributed CRM entries: a client's objection gets logged as something the sales rep said, or a commitment the client made gets recorded as an offer the rep extended. The mechanism that prevents a compounded diarization error from turning into a committed business record is a human review step, where the AI proposes an action item or CRM entry and a person approves it before it gets written anywhere permanent. Without that review-and-release control, a hallucinated or misattributed action item creates a form of exposure that the pre-AI, manually-typed workflow never carried at all.
Evaluating diarization quality in a meeting tool
Because a vendor's DER number and a polished demo call will not reveal how a system actually behaves on overlapping speech, evaluating a meeting tool means testing the specific conditions where diarization quietly breaks. A few concrete checks surface that behavior faster than reading a spec sheet.
Test the tool on your own audio rather than relying on a vendor's demo. Every system performs well on a clean two-person call. The real signal is how it handles a four-person meeting with frequent cross-talk, scattered back-channels, and at least one non-native speaker in the mix.
Ask directly whether overlapping speech gets attributed to both speakers or simply discarded. Masking keeps the speaker labels looking clean, but it does so by dropping the overlapping words. A system that treats overlap as something to resolve and attribute correctly, rather than something to cut out, is doing meaningfully harder work and should be evaluated accordingly.
Pull a transcript from a meeting where several people made commitments and check the action-item attribution by hand. Confirm that each item is assigned to the person who actually said it, not to whoever happened to be speaking immediately before or after.
Ask what metric the vendor actually reports. A vendor who reports only DER is not measuring whether the right words ended up in the right speaker's column. Ask whether they also track concatenated minimum-permutation word error rate, or some equivalent measure of attribution accuracy, since that is the number that actually reflects whether a transcript assigns speech to the correct person rather than simply drawing clean-looking boundaries.
Finally, test in the languages and accents the team actually uses day to day, since overlap-handling methods trained and tuned on one language distribution carry no guarantee of performing the same way on another. The diarization error rate on a vendor's slide describes a benchmark condition. The transcript a meeting tool produces next week describes a conference room, with its own speakers, its own accents, and its own overlapping voices, and that is the condition the evaluation needs to match.
Sources
- Overlap-Adaptive Hybrid Speaker Diarization and ASR-Aware Observation Addition for MISP 2025 Challenge
- The BUCEA Speaker Diarization System for the VoxCeleb Speaker Recognition Challenge 2022
- The ByteDance Speaker Diarization System for the VoxCeleb Speaker Recognition Challenge 2021
- The tttAI System for the TSA-ASR Task of the SmartGlasses Challenge 2026
- M2MeT: The ICASSP 2022 Multi-Channel Multi-Party Meeting Transcription Challenge
- arxiv.org